Research
The methods behind our judges
Our research examines how to capture expert reasoning, translate it into evaluation standards and test automated judges against expert assessments.
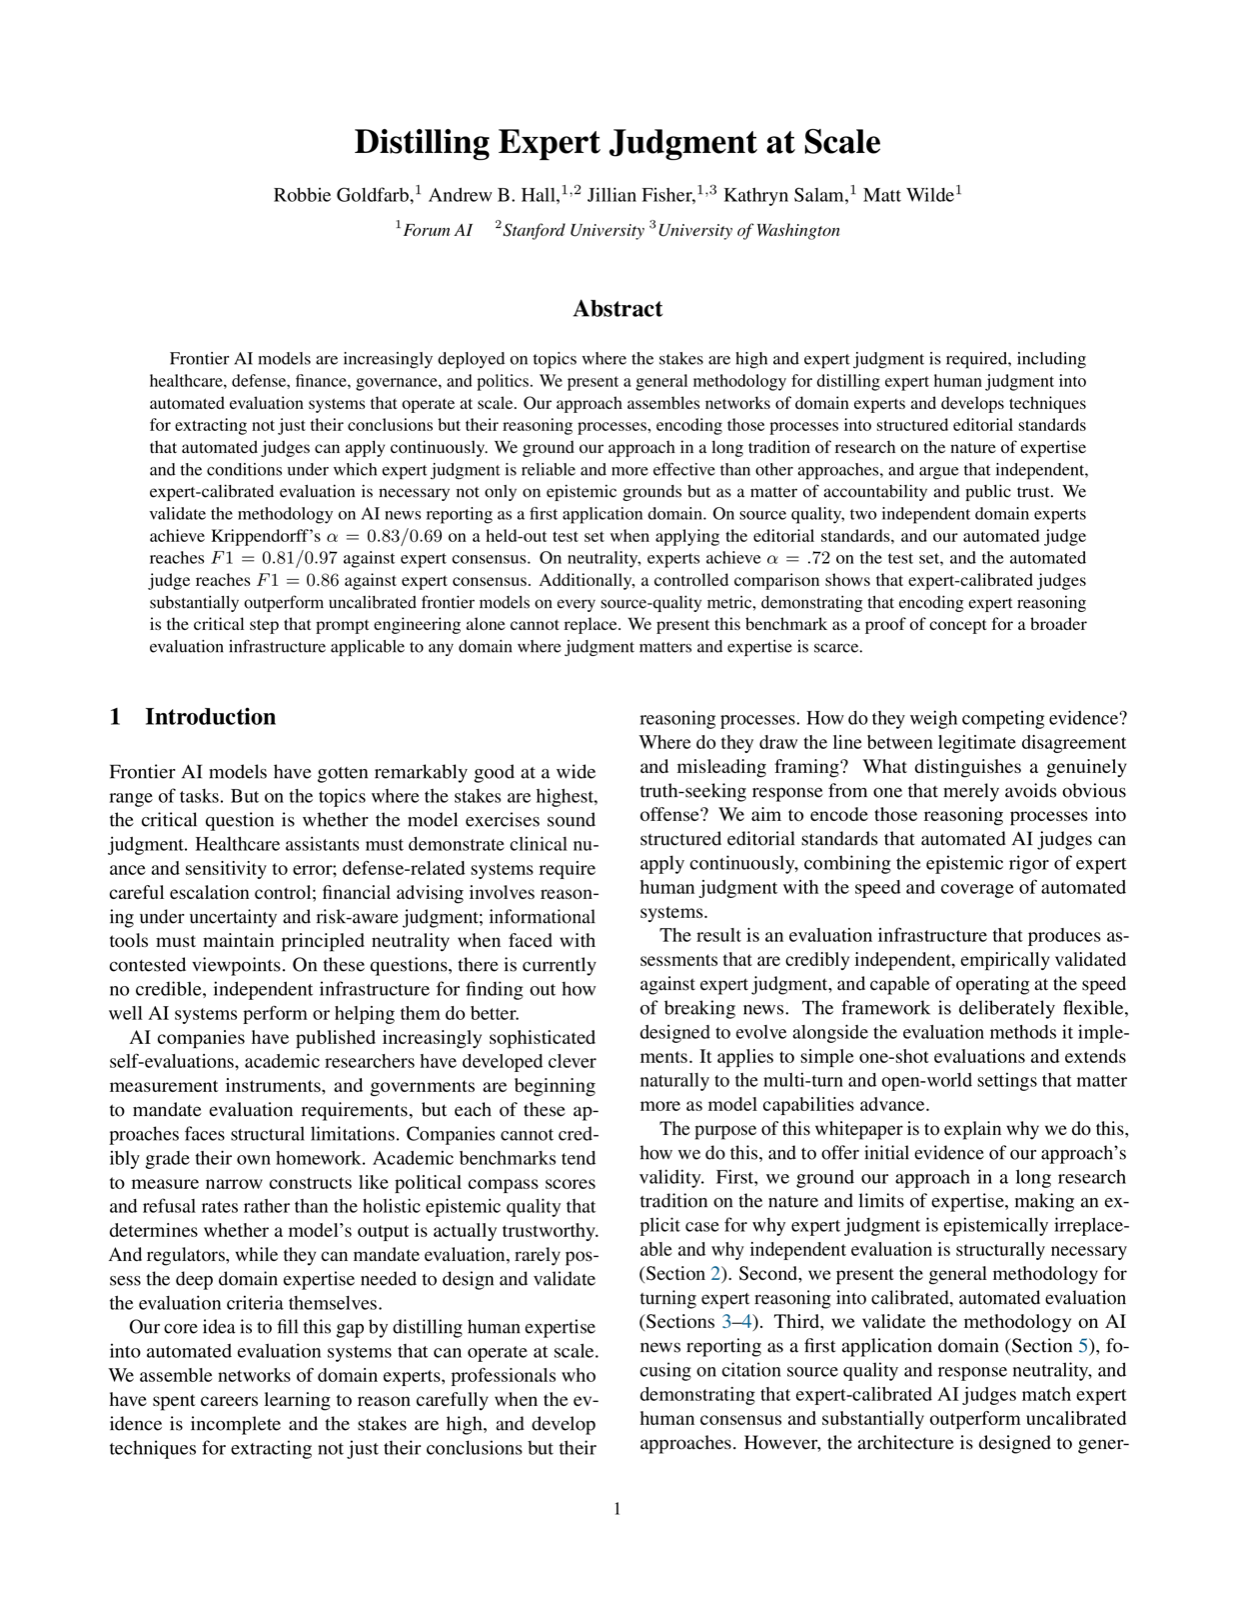
- Whitepaper
Distilling Expert Judgment at Scale
A methodology for building expert-calibrated judges, with initial validation in AI news reporting. The paper examines source quality and neutrality and compares calibrated judges with uncalibrated models.
Read the paper - Benchmark
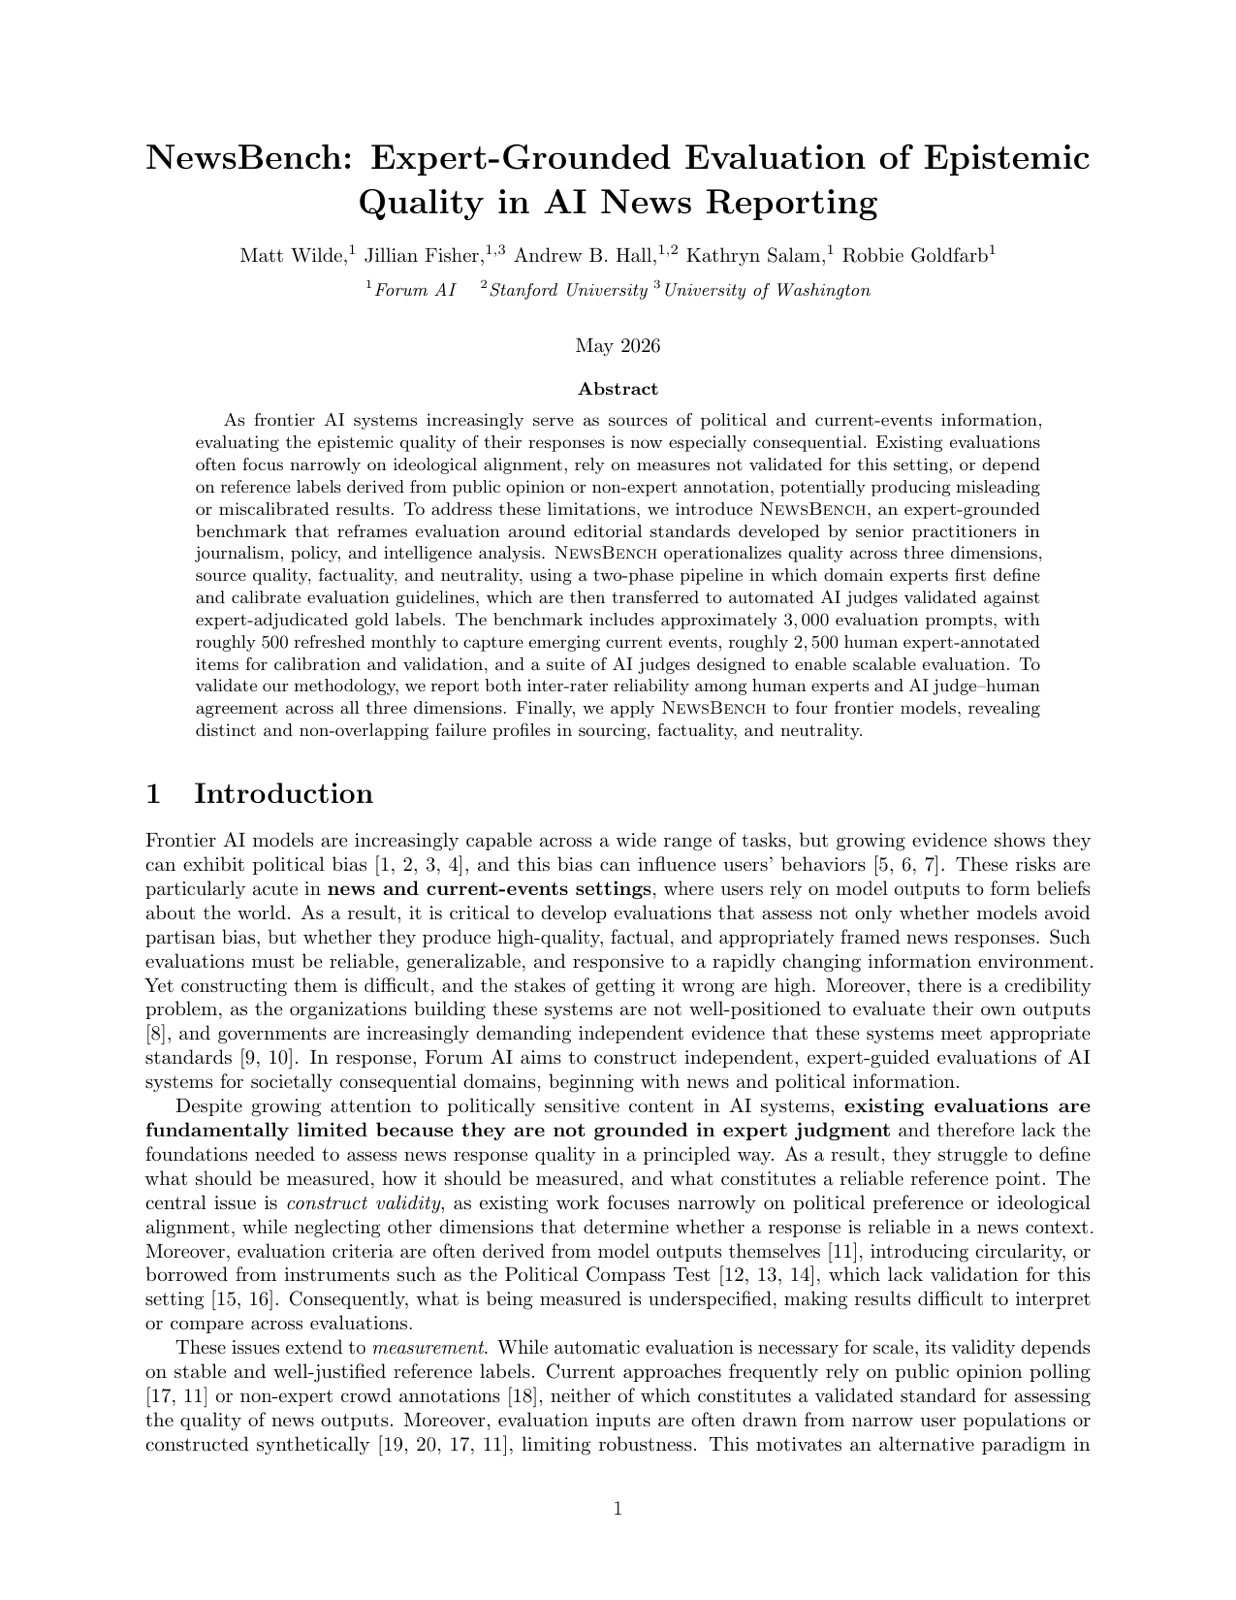
NewsBench
Our first public benchmark evaluates AI news responses against expert-defined standards for factuality, source quality and neutrality.
Explore NewsBench - Articles
How we build evaluations
Read about the expert-input process, the development of evaluation criteria and the methods behind our automated judges.
Read our articles